 Legal
Mass Tort Intake AI: Litify vs Filevine vs Custom Agent
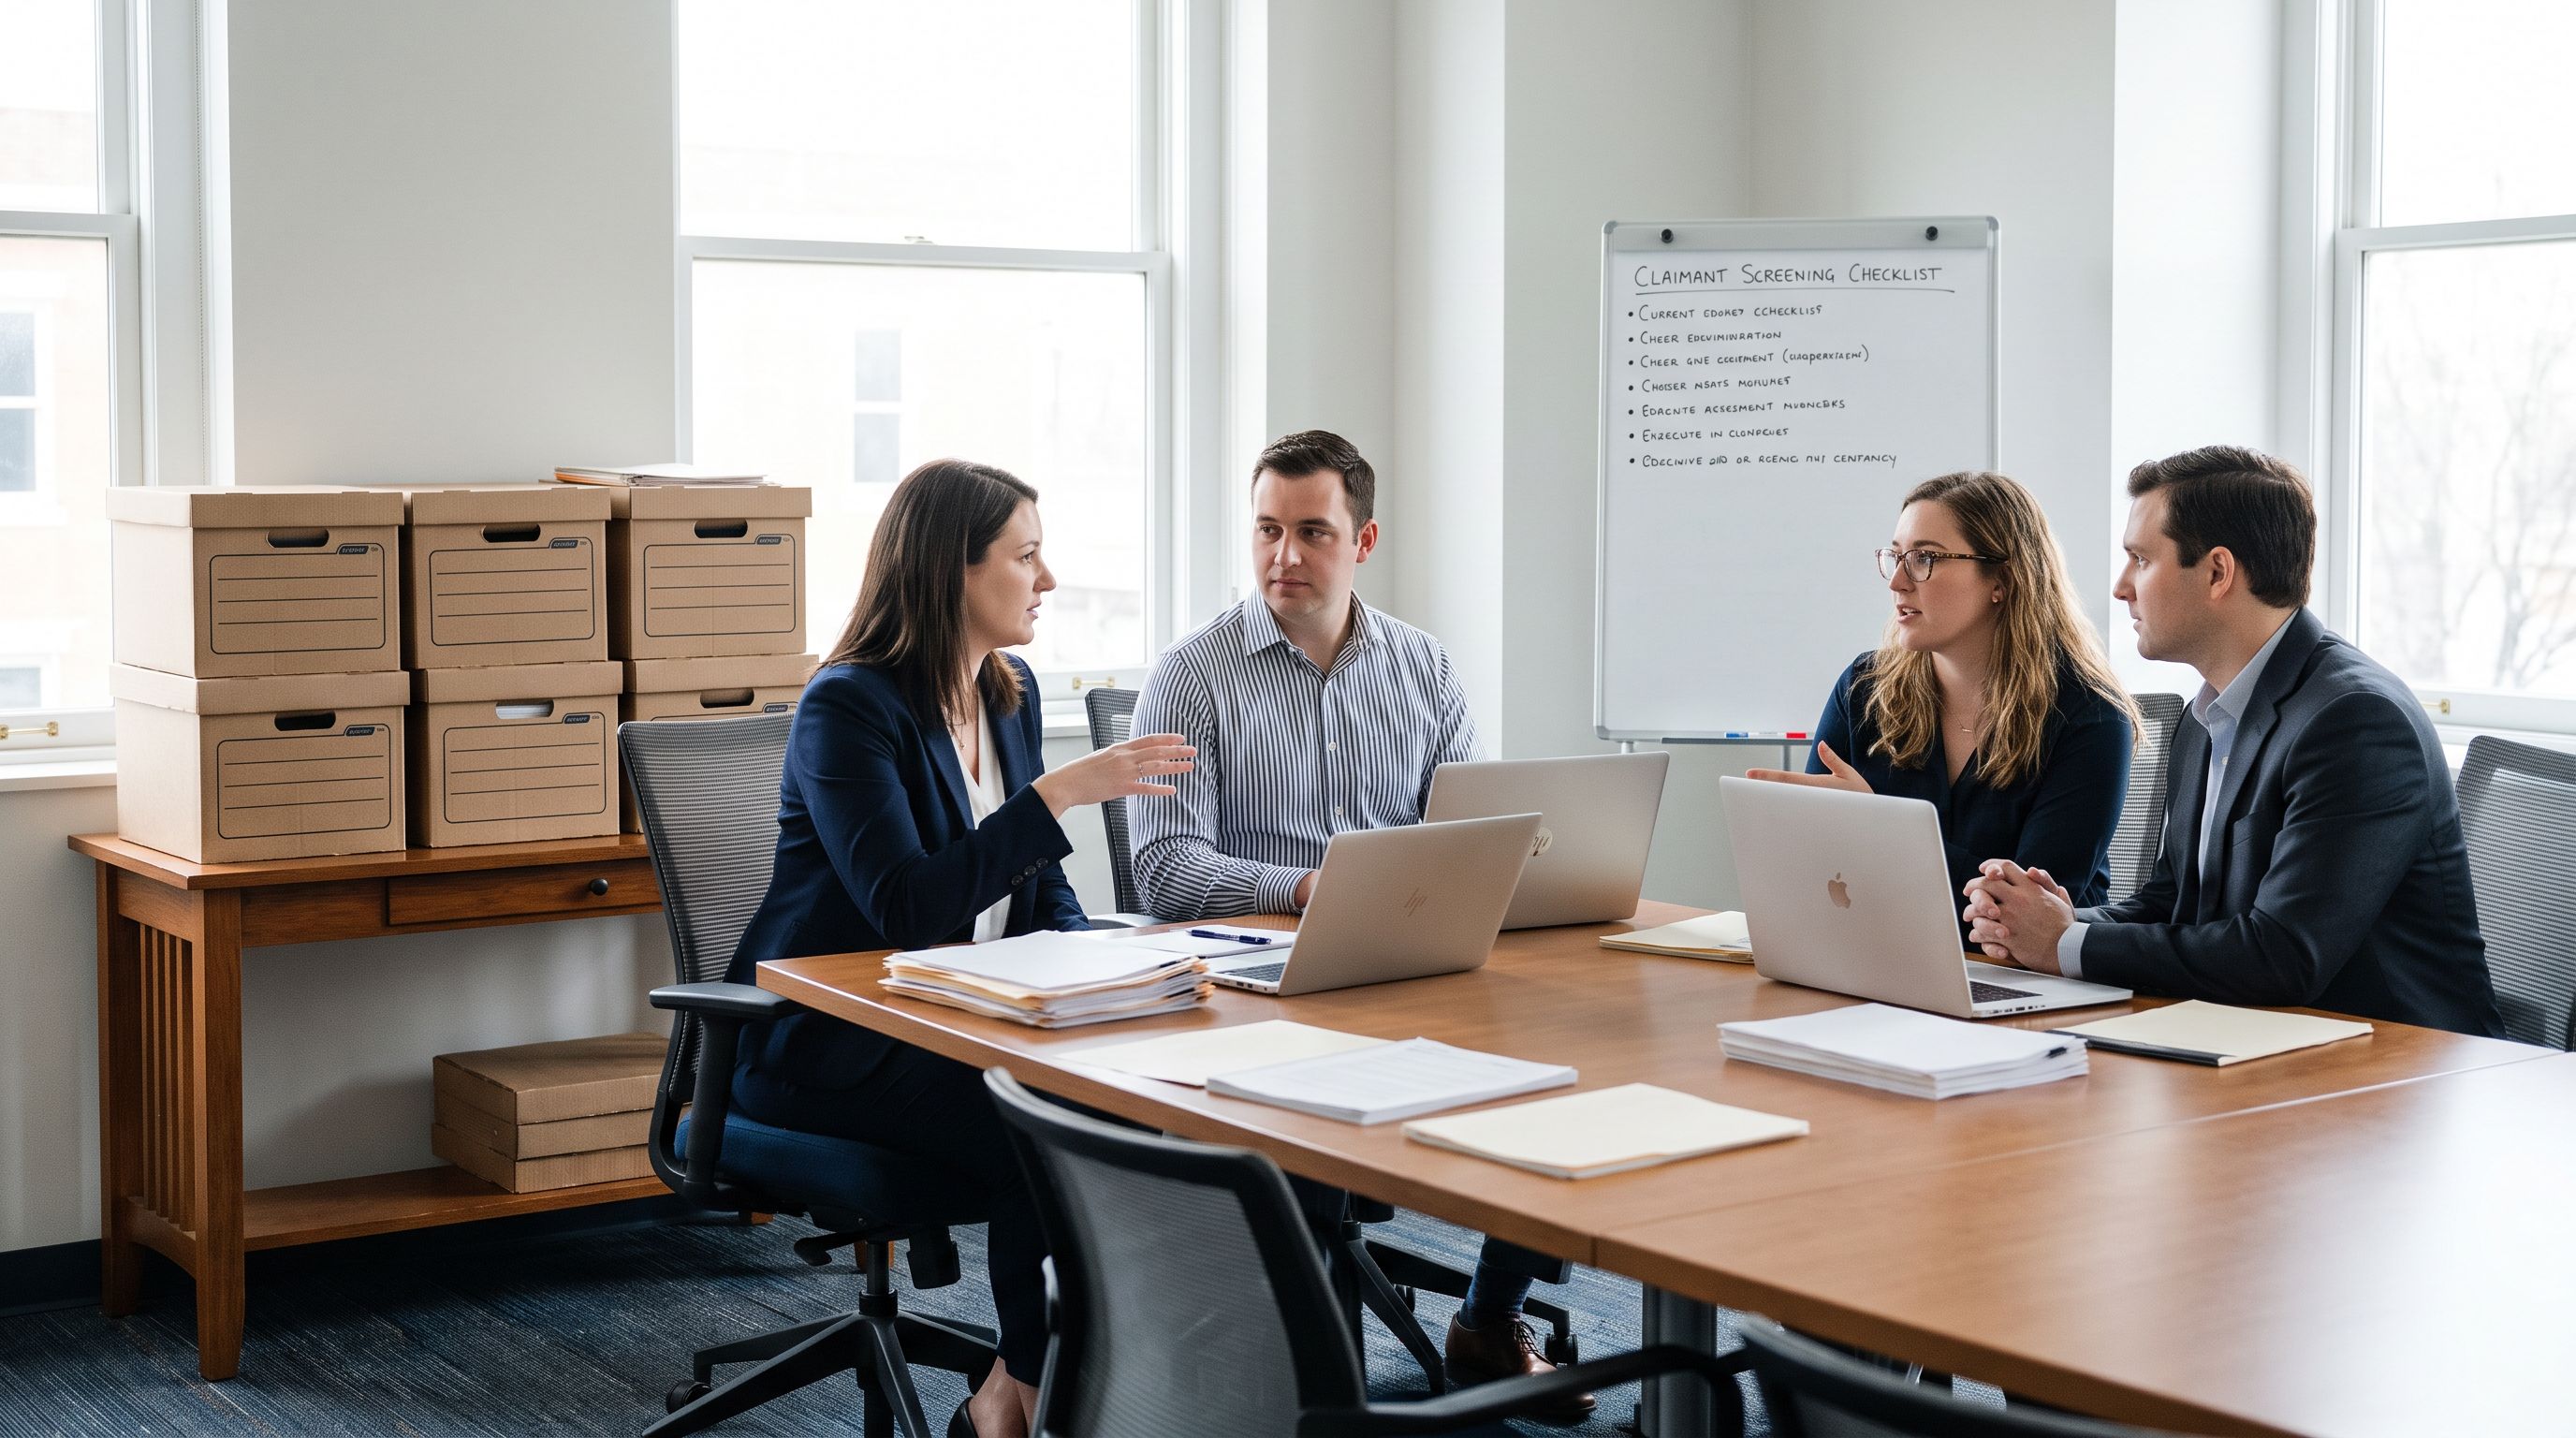
The job is eligibility screening, not form-filling
If your firm takes on mass tort or high-volume claimant work, the intake bottleneck is rarely typing. It’s the judgment layer underneath:
- Did this claimant actually use or encounter the product, and can they identify it?
- Do the use dates and injury dates fit the court’s inclusion criteria?
- Does the diagnosis match the compensable injury list, or is it adjacent?
- Which state’s statute of limitations applies, and is the claim already stale?
- Have we signed this person before, under a different phone number, from a different lead vendor?
- Can we produce a complete plaintiff fact sheet (PFS) before the deadline in the case management order?
That last one is where firms bleed. MDL courts commonly manage claimant volume through plaintiff fact sheets, census or registry filings, and deficiency procedures set by case management order, and some transferee judges have entered Lone Pine–style orders requiring prima facie proof of exposure and causation before a case proceeds — the label traces to Lore v. Lone Pine Corp., an unpublished 1986 New Jersey Superior Court decision. None of this is uniform. Start with the Judicial Panel on Multidistrict Litigation’s pending MDL list at jpml.uscourts.gov to confirm the transferee court, then pull the actual orders from that court’s docket; several transferee courts publish them on a dedicated public MDL page, as the Northern District of Ohio does for the opioid MDL (MDL 2804). Encode what the current order says, verified by counsel on the case — not what the last campaign required.
What AI agents do well — and how to catch them failing
An AI agent, unlike a chatbot, carries out a multi-step task and takes actions: pull the intake transcript, read the pharmacy printout, compare against this campaign’s criteria, write a summary into the matter, assign a paralegal task. That maps well to claimant screening, because the work is repetitive, document-heavy, and rule-driven.
Where agents genuinely help: extraction from messy sources (call transcripts, implant and pharmacy records, DD-214s, hand-filled questionnaires); fuzzy deduplication across lead vendors on name, DOB, address history, and phone; criteria checks that cite the record they relied on; and PFS pre-screening against the court’s required fields before you serve it.
Where they break — each paired with a signal you can actually monitor:
- Statute of limitations. Discovery rules, tolling, and borrowing statutes are state-specific and fact-dependent. Treat output as a flag, never a determination. Signal: track the share of agent SOL flags an attorney overturns on review, week over week. A moving overturn rate means your skill, your data, or the underlying model changed — stop and re-test.
- Anything verified under oath. A PFS verification is an attestation. Agent-drafted, human-verified. Signal: require a logged human verification event on every served PFS. If your system can’t produce that log on demand, you can’t evidence supervision.
- Adversarial documents. Third-party records and PDFs can carry text that hijacks a naive agent; see prompt injection defenses for legal documents. Signal: log every agent action whose triggering instruction originated inside an ingested document rather than from a staff prompt, and review that log weekly. It should normally be empty.
- Supervision duties. ABA Model Rule 5.3 addresses responsibility for nonlawyer assistance, and Comment 8 to Model Rule 1.1 addresses technology competence. Your state’s version controls — check your bar’s ethics opinions. Signal: a named supervising attorney per campaign, in writing, with the review queue assigned to them.
An agent that screens out one ineligible claimant before you order records has already done more for the P&L than one that drafts a prettier intake summary.
Three platforms, three different shapes
Their AI features converge on similar promises; their underlying architecture doesn’t, and that’s what constrains you.
Litify is built natively on Salesforce. You inherit the Salesforce data model, sharing and permission rules, reporting, and the surrounding app ecosystem — powerful if you have admin capability, configuration-heavy if you don’t. Campaign-level screening logic tends to live in Salesforce-native automation.
Filevine is document- and workflow-centric: matter templates, document generation, deadline chains. Firms that organize work around producing and chasing documents often find its structure closest to how mass tort intake actually runs.
CASEpeer is PI-first and opinionated out of the box, with intake and case workflow prebuilt rather than assembled. Strength is speed to deploy; the limit is bending a plaintiff-PI shape around novel mass tort criteria.
Strengths: one vendor, one security review, one support line. The AI sits on your claimant records with no integration work. For a firm running two or three campaigns on stable criteria, this is usually enough.
Limits: you get the vendor’s idea of screening. Per-campaign criteria changes often mean new fields and manual review rather than a reasoning step. Records outside the platform — an SFTP drop from a records vendor, a lead vendor’s portal — may be out of scope.
What it is: an AI assistant (Claude or similar) connected through MCP — an open standard for governed access to specific tools and data — to your case manager, document store, and records feed. You define skills: packaged instructions that make it screen the same way every time, per campaign.
Strengths: criteria live in a versioned skill file you can change the day a CMO changes. The agent reaches across systems the platform can’t see. Output format is yours, including this MDL’s exact PFS field list.
Limits: the cost is recurring, not a one-time build. Budget for token/API spend that scales with volume, maintaining and re-running the evaluation set after every model or criteria change, credential rotation and access reviews, log retention, and — the largest line — a named owner’s ongoing time to notice drift.
There’s a third option people skip: don’t automate the judgment at all. One campaign, fifty claimants, stable criteria — a sharp paralegal with a two-page checklist beats both options on cost and reliability.
A workable build, step by step
-
Write the screening criteria down first
Inclusion criteria, exclusion criteria, required proof for each, and what “ambiguous” looks like. If you can’t write it as a checklist, an agent can’t execute it. -
Start read-only
Read access to intake records and documents, write access to nothing. Let it produce a screening memo per claimant for two weeks while humans decide. See read-only vs write access for legal AI agents. -
Build a golden set
Pull 30–50 already-decided claimants: accepted, rejected, borderline. Score against known outcomes, tracking false accepts separately from false rejects — they cost different amounts. -
Grant narrow write access
Once accuracy holds, let it create tasks, populate PFS drafts, and post a structured screening note. Still no retainer sent, no claim filed, no record ordered without a human click. -
Route the gray zone to people
Clean accepts and clean rejects go to a spot-check queue; anything ambiguous routes to a named reviewer with the agent’s reasoning attached. -
Re-test every campaign
New MDL, new criteria, new skill version, new golden set. Accuracy is campaign-specific, not universal.
Model the money with your own numbers
Don’t take anyone’s ROI headline, including ours. The example figures below are illustrative placeholders, not benchmarks — replace every one with a measurement from your own pipeline.
| Input | Example assumption (replace) | How to get your number |
|---|---|---|
| Leads screened per month | 400 | Count from your intake system |
| Human minutes per screen | 12 | Time ten real screens |
| Screening hours/month | leads × minutes ÷ 60 | Arithmetic |
| Ineligible claimants signed/month | measure | Dismissals traced back to intake |
| Cost per ineligible sign | measure | Records fees + intake labor + seat cost |
Gross benefit is hours saved × your loaded hourly cost, plus ineligible signs avoided × cost per sign. Then subtract honestly: platform seats or build-and-maintain cost, review time (an agent needing 10 minutes of checking per claimant saved 15 minutes, not 25), and the ramp where output trails your paralegal. The fuller framework is in the law firm automation ROI walkthrough.
How to choose
Opinion, stated plainly: if you’re already on Litify, Filevine, or CASEpeer, run the platform’s AI for a full campaign and document exactly where it falls short. Firms that commission a custom agent before they can name three specific failures of their current platform tend to rebuild features they already pay for.
Go custom when (a) criteria shift per campaign faster than configuration can follow, (b) decisive records live outside the case manager, or (c) deficiency and dismissal rates are material and traceable to inconsistent screening. Stay manual when volume is low or criteria are still being negotiated.
Whichever you choose: lead-source compliance, solicitation rules, and fee-sharing in mass tort work are governed by your state’s rules of professional conduct and by the MDL’s own orders. Confirm those with qualified counsel or your bar’s ethics line before the campaign starts, not after.
Related reading: AI medical record review and chronology building · building a custom MCP server over your firm’s matter data · agentic discovery triage for small firms
Where is your firm losing billable hours?
Get a free automation audit: we map your intake-to-invoice workflow and show you exactly what's worth automating — before you spend a dollar.
Get a free automation auditRelated guides
Expert Witness Vetting: AI Platforms vs Custom Agent
An honest comparison of AI expert witness research options for small firms — specialist platforms, litigation analytics, and a custom Claude + MCP agent.
Read guide →
Law Firm AI Pricing: Per-Seat vs Usage vs Custom Build
Legal AI pricing is shifting from per-seat to usage and outcome models. Compare the three shapes, what a custom build really costs, and how to budget it.
Read guide →
Contract Management for Law Firms: CLM vs Clio vs Agent
Contract management software for law firms compared: off-the-shelf CLM, your practice management system, or a custom AI agent for obligation tracking.
Read guide →